Open-source measurement harness for Factory Droid agents
Grade the commit,
not the narration.
droid-tune runs coding tasks through an agent in an isolated git worktree, grades the resulting commit with deterministic behavioral tests, and writes an evidence pack for every attempt — so a result can be audited later instead of trusted.
The finding that motivates the project
Four models fixed the bug.
Seven of eight attempts submitted nothing.
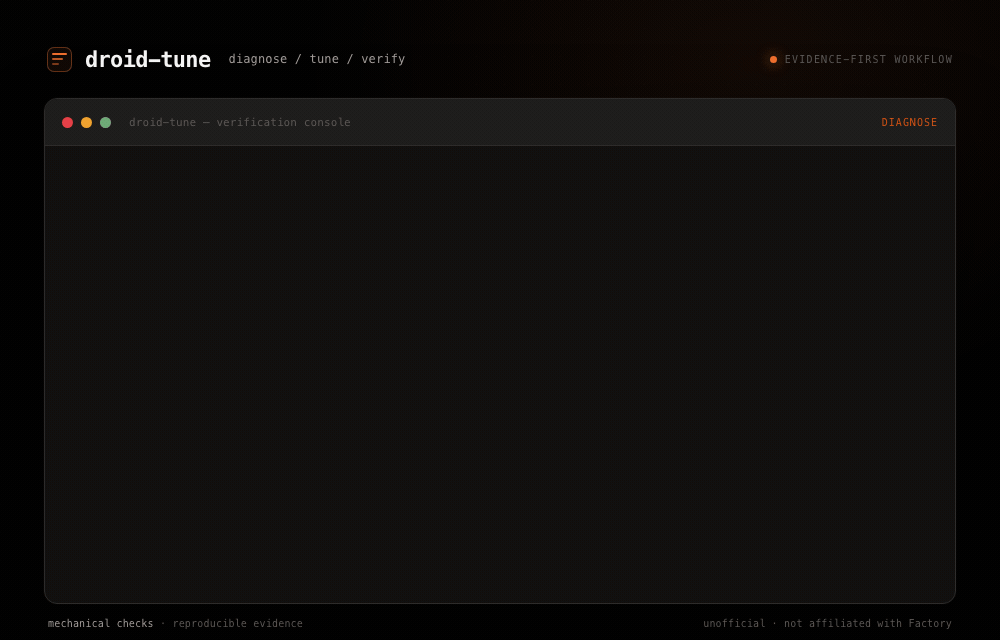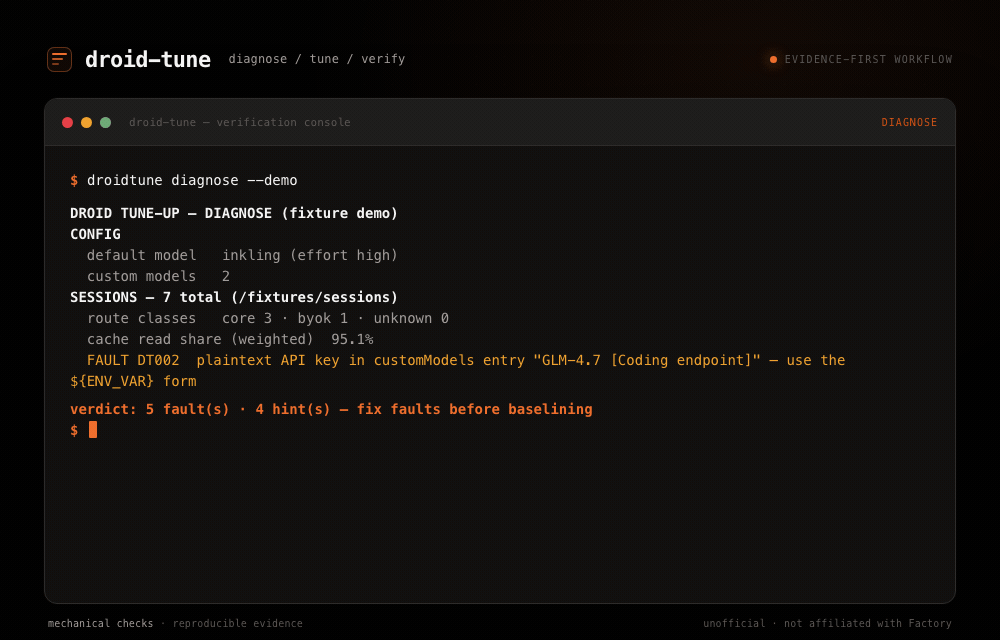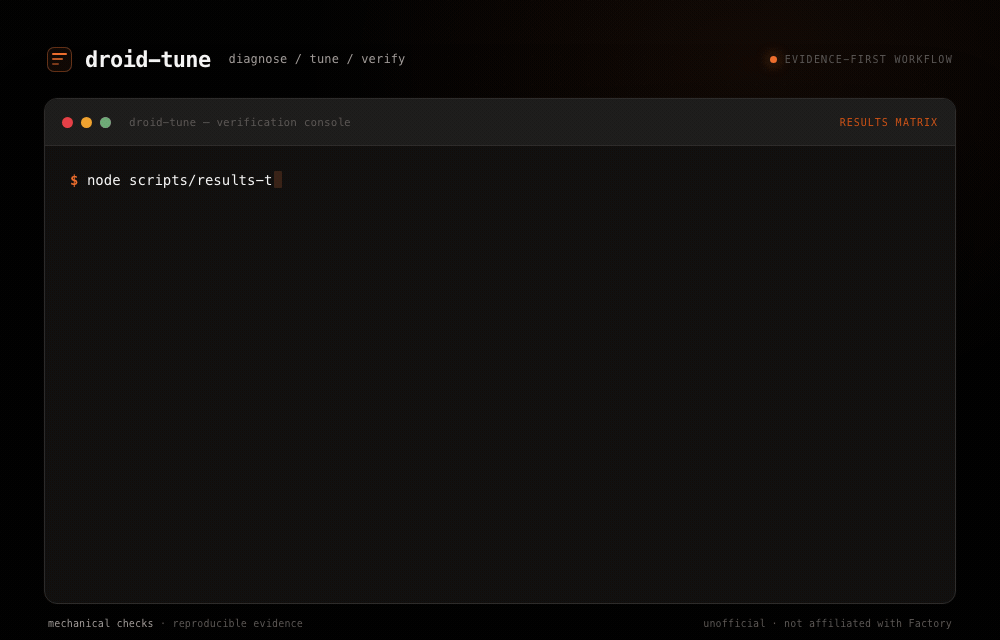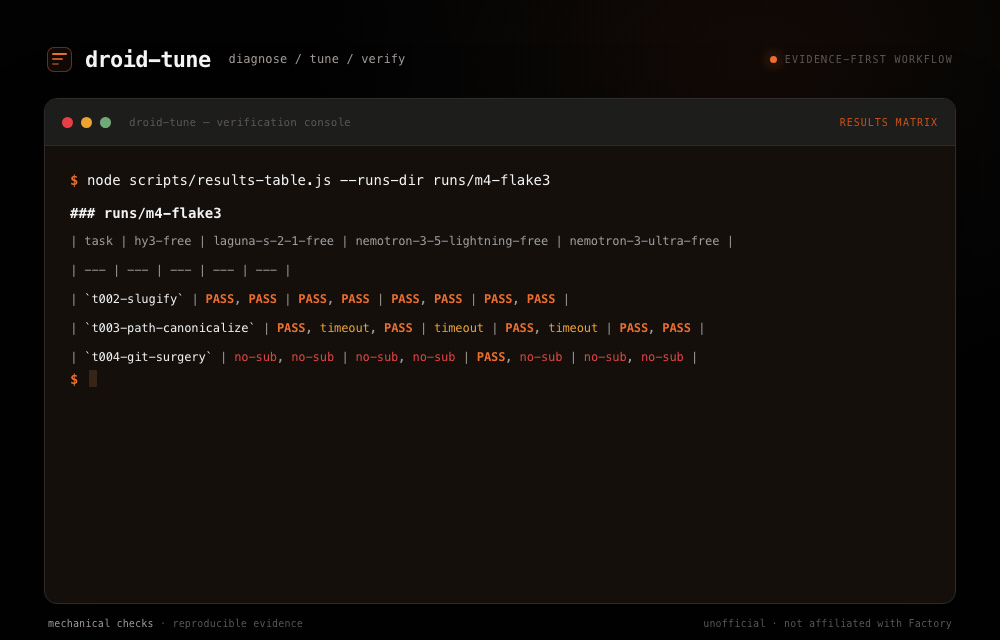
The task t004-git-surgery asks the agent to repair a broken git
history and says, explicitly: commit your result. Across a 40-trial
live flake check, four different models repaired the history correctly and
then never ran git commit.
7 of 8 attempts were classified NO_SUBMISSION.
A file-content or diff check would have passed these seven — it can
miss an absent commit the task explicitly required. The work was done,
sitting uncommitted in the worktree. droid-tune grades
the commit, so it fails them. The one
nemotron-3.5-lightning-free attempt that did commit also passed.
This is the gap the tool exists to measure: the difference between an agent that did the work and an agent that delivered it. A transcript tells the first story. Only the commit tells the second.
What every trial produces
An evidence pack, not a score.
Every claim-eligible trial writes a complete, hash-manifested pack. If the pack is missing the transcript, the verifier provenance, or the pricing snapshot, the tool will not make the claim. The bar is mechanical: the tool must be incapable of stating a claim the evidence doesn't support.
-
manifest.jsonSHA-256 manifest of every artifact in the pack. -
results.jsonThe outcome class — VERIFIED_PASS, NO_SUBMISSION, and the rest — from deterministic behavioral tests. LLM judges are barred from pass/fail. -
transcript.jsonlThe full session, kept for offline audit. -
patch+ frozentests/The graded diff and the exact test tree that graded it. The agent worktree never containstests/orsolution/. - Provenance Which model, which tune and its hash, which runner SHA — so a number can be traced back to the exact configuration that produced it.
Recorded result, raw evidence not included
Cache-stability study record.
The native-Droid dt-v0-cache-stability comparison was
registered before its 50 confirmatory trials and reported on
2026-09-03. The committed conclusion records
88.0% first-pass yield, compared with 84.0% for
native Droid, while observed Factory Standard Credits per verified
task fell from 11,387.3 to 9,010.9.
The frozen descriptive conditions were met, but the raw evidence
is under ignored runs/ paths and is not included in a
fresh clone. Yield differs by one pass (22/25 versus 21/25); the
rule has no uncertainty threshold. This is not an independently
reproduced recommendation or proof of general improvement.
Evidence limits and recorded conclusion.
The preregistered claim — published in full
The flagship result is a null result.
dt-v1-ledger-lite-nosub was registered before running:
a frozen decision rule, a pinned tune hash, a required effect size. The
hypothesis — a 1,721-byte tune file, pinned by hash in the claim,
would cut the NO_SUBMISSION rate by at least 25 percentage points.
80 trials later (2 arms × 4 routes × 10 attempts), the decision rule was computed without re-cutting the metric.
Result: NOT SUPPORTED. The tune moved NO_SUBMISSION 5.0 percentage points against a required 25. The hypothesis failed, and the failure is published in full — see the public claims registry & results report — because a tool that only publishes its wins is not a measurement tool.
| Metric | Control | Tuned |
|---|---|---|
| NO_SUBMISSION | 85.0% | 80.0% |
| VERIFIED_PASS | 15.0% | 20.0% |
Δ = 5.0pp vs 25pp required · two-sided Fisher exact p = 0.7695 · NOT SUPPORTED
Committed, reproducible, or both
The numbers, all of them.
Every statistic on this page is one of these. There are no others.
- 29 / 40
- VERIFIED_PASS — 40 repeated attempts across 5 tasks and 4 free routes, at $0 observed inference cost (free BYOK routes; excludes subscriptions and credentials). A live flake check.
- 13 / 23
- VERIFIED_PASS (57%) in the committed demo pack, 3 tasks × 4 routes — regenerable by anyone from the repo.
- 0 / 8
- configured free routes currently marked up by the committed weather badge. Failures remain recorded as data.
- 80
- trials in the preregistered dt-v1 sweep: 2 arms × 4 routes × 10 attempts. Null result, published.
- 506
- tests observed by
npm run checkon 2026-09-02, including re-derivation checks that fail CI if a committed report drifts from its evidence. - 0
- runtime dependencies. Node ≥ 20, ESM. Nothing to install but the repo itself.
Reproduce it yourself
Quick start.
Clone and run the suite
git clone https://gitlab.com/sxanz/droid-tune
cd droid-tune
npm test
Install as a Droid plugin
droid plugin marketplace add \
  https://gitlab.com/sxanz/droid-tune
droid plugin install \
  droid-tune@droid-tune --scope user
Running trials against models requires your own credentials; free routes are probed daily and the results are committed as data. The demo pack regenerates offline, with no credentials and no network — that is the number a stranger can check without spending anything. The live-route figures come from trial transcripts that are not committed, so they are reported, not reproducible.